

Together AI
24 Case Studies
A Together AI Case Study
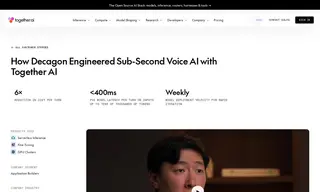
Decagon, a company that builds conversational AI agents for enterprise customer experiences, faced the significant challenge of engineering a voice AI system capable of sub-second latency. Voice interfaces require instantaneous responses, as any delay causes users to lose trust. Decagon's multi-model architecture further complicated serving, making it difficult to achieve this strict latency budget while managing costs and enabling rapid iteration. To address this, they partnered with vendor Together AI, leveraging their Serverless Inference and GPU Clusters.
Together AI implemented a solution using NVIDIA Blackwell GPUs and optimizations like speculative decoding with custom-trained models and prompt caching. This partnership resulted in a dramatic reduction in both cost and latency. Decagon achieved a 6x reduction in cost per turn and reduced p95 model latency to under 400ms, enabling a truly conversational voice experience that customers positively acknowledge. Together AI's infrastructure also provided the stability needed to handle traffic surges and the flexibility for Decagon to deploy new models weekly.
24 Case Studies