

Baseten
23 Case Studies
A Baseten Case Study
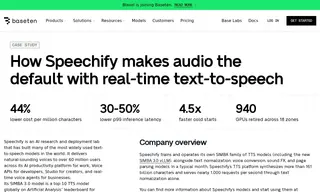
Speechify, a leading AI text-to-speech platform with over 60 million users, faced significant challenges managing its own inference infrastructure. Before partnering with Baseten, the complexity of their self-managed stack, which spanned 1,500 GPUs, slowed down model deployments and resulted in long cold starts. Their engineering priority was to reduce this operational overhead and improve latency for their new SIMBA 3.0 model to ensure the best user experience.
By moving its text-to-speech workloads to Baseten, Speechify implemented a solution using Truss for model deployments and leveraged Baseten's traffic-based autoscaling and multi-region inference. The results were substantial: Baseten helped Speechify achieve a 44% reduction in cost per million characters, a 30-50% decrease in p99 inference latency, and 4.5x faster cold starts. This allowed Speechify to retire 940 GPUs and free its engineering team to focus on product innovation.
23 Case Studies